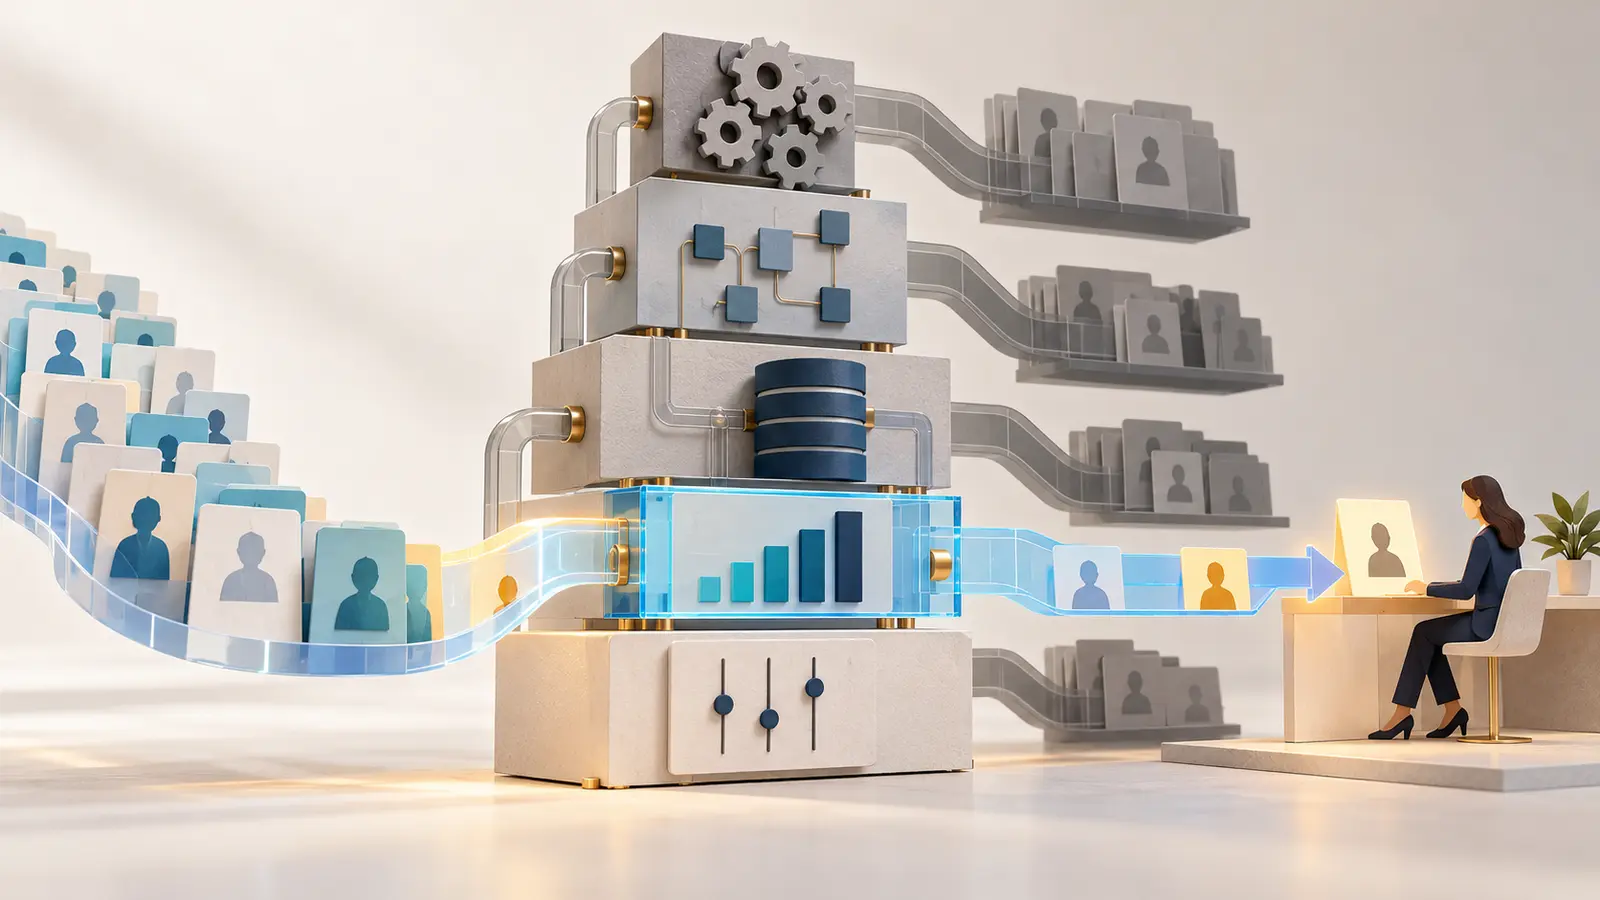
Direct answer: most midsize companies should not begin with a custom model. Use transparent rules when volume, history, or outcome definition is weak. Use CRM-native scoring when data, decision, action, and feedback live mostly in the platform and the feature provides adequate segmentation, explanations, integration, and monitoring. Build a custom model only when a material decision depends on signals across systems, a measured native baseline has a documented limitation, and the company can operate point-in-time history, evaluation, logging, monitoring, incidents, retraining, and rollback.
The question is not which algorithm looks more sophisticated. It is which architecture improves a queue, outreach motion, SLA, nurture path, or budget with better evidence and proportionate operating cost. If sales does not know what to do with the score, the outcome is ambiguous, or the CRM does not record what happened, changing models only automates an incomplete decision.
Start with the decision the score controls
- Unit — person, account, opportunity, or another object; do not mix grains.
- Outcome — acceptance, held meeting, opportunity, order, revenue, or margin with a maturation window.
- Action — prioritize, route, nurture, suppress, research, or take no action.
- Capacity — how many records the team can work within an SLA and with what treatment.
- Error — the cost of prioritizing noise, missing real demand, or creating unequal treatment.
- Comparator — the current queue, a simple rule, native score, or documented human policy.
- Feedback — who returns the outcome and reason, how quickly, and at what quality.
A score without a defined action becomes CRM decoration. The qualification and handoff workflow at https://makinai.co/insights/en/ai-lead-qualification-marketing-sales-handoff turns ranking into observable sales work. Define abstention too: insufficient evidence can trigger enrichment or review rather than a number with false precision.
The Lead Scoring Architecture Ladder
- Level 0: repair without a model — fix identity, fields, lifecycle, labels, SLA, and ownership before scoring.
- Level 1: rules and weights — explainable criteria, decay, exclusions, and bands that operations can review.
- Level 2: CRM-native predictive scoring — configuration, training, and scores stay close to objects, workflows, lists, and reports.
- Level 3: managed external batch model — a warehouse or service computes scores and returns value, version, and reasons to CRM on a defined cadence.
- Level 4: custom decision service — point-in-time features, endpoint, low latency, multiple actions, observability, fallback, and continuous operations.
Move up only when the current level fails a requirement that creates value. Rules fit when commercial policy matters more than subtle patterns or mature outcomes are scarce. Native scoring reduces integration and places the score where users work. External batch adds flexibility without assuming real time. A custom service is justified when several sources and decisions reuse a governed layer and latency actually changes the action.
Salesforce documents conversion-history models, segmentation, and influential factors. HubSpot lets teams select a lifecycle transition and evaluation window and publishes a sample minimum for generating an AI score. Microsoft exposes scores, reasons, and different refresh behavior for new and existing records. These features do not prove economic fit, but they show that native capabilities can cover much more than a manual point system.
Pass seven gates before building
- Decision and value — does the potential change in pipeline, revenue, margin, or capacity justify the project?
- Definition and maturation — are outcome, window, entity, and denominator stable enough to evaluate?
- Point-in-time data — did features exist at decision time with known coverage, permission, and provenance?
- Baseline — were the rule and native feature configured and compared fairly?
- Action and adoption — does the score enter a workflow, queue, and SLA; can users understand reasons and return feedback?
- Operations and risk — are versioning, logging, monitoring, fallback, incident ownership, and rollback real?
- Economics and exit — are total cost, portability, documentation, and a path back to the prior level explicit?
When a gate fails, the next investment is usually system repair rather than model building. The minimum-evidence guide at https://makinai.co/insights/en/how-much-historical-data-first-ai-marketing-workflow separates inadequate history from inadequate value. The historical architecture at https://makinai.co/insights/en/feature-store-cdc-snapshots-minimum-crm-history-architecture-ai explains why governed snapshots may be enough before a feature store, CDC, or online serving.
Compare total cost—not just license or training
For native scoring, include licensing, configuration, field mapping, cleanup, segmentation, workflows, user enablement, error review, reporting, and operations. For an external model, add a warehouse, point-in-time transformations, development environment, evaluation, batch execution, return integration, alerts, and support. For a custom service, add endpoints, capacity, security, observability, incidents, refreshes, documentation, regression tests, and on-call coverage.
Cost also depends on outcome delay, markets and products, languages, entities, volume, schema stability, scoring frequency, explanation requirements, and error impact. Real time is expensive when it changes only the speed of the number rather than the speed of the action. Customization creates value when it removes a measured limitation, not when it recreates a native feature behind another interface.
Use three denominators: cost per scored record, cost per decision actually executed, and cost per incremental outcome or validly redeployed capacity. The first measures infrastructure, the second exposes adoption, and the third requires a credible comparison or an explicit attribution limit.
Illustrative example: three markets, one score
Consider a B2B company with 30,000 annual leads, 800 opportunities, and sales in the United States, Brazil, and Mexico. Its CRM-native feature can train on opportunity conversion, create segments, and expose reasons. Before funding custom modeling, the team compares it with the current queue and a simple rule for six weeks. The largest loss is not ranking: Mexico records outcomes late, while Brazil combines demo requests and content downloads in one lifecycle stage.
The right decision is to stay native, repair lifecycle and feedback, and segment the population. A custom model enters the backlog only if product, billing, or intent signals outside CRM produce a stable gain on mature outcomes after the repair. The example is illustrative; raw volume does not guarantee useful labels or statistical viability.
A comparable six-week pilot
- Week 1 — select one decision, mature outcome, population, window, capacity limit, and current policy.
- Week 2 — reconstruct a point-in-time sample; document coverage, unknowns, exclusions, and feedback delay.
- Week 3 — implement or repair a simple rule and native score with the same permitted data and segments.
- Week 4 — run rule and native score in shadow; review ranking, calibration, reasons, errors, and queue impact.
- Week 5 — test an external approach only if a limitation is documented; keep the same window, baseline, and treatment.
- Week 6 — compare executable decisions, mature performance, operations, risk, and total cost; stay, repair, move up, or stop.
Deliverables: decision contract, data inventory, baseline, native configuration, evaluation dataset, segmented comparison, TCO estimate, risk log, operating plan, and decision record. Do not accept a demo on selected data as evidence of superiority.
Ownership, monitoring, and exit
Marketing defines population, treatment, and commercial outcome. RevOps owns lifecycle, labels, capacity, and workflow. Sales executes the action and returns disposition. Data owns history, identity, quality, and replay. Data science evaluates baseline, calibration, and uncertainty. Technology operates integration and service. Finance validates cost and value; compliance reviews attributes, explanation, and group effects.
A custom model inherits obligations that the platform previously absorbed. Google Cloud makes schema, baseline, objectives, thresholds, and alerts explicit in model monitoring. NIST calls for lifecycle measurement and documentation of uncertainty, feedback, and failures. The drift guide at https://makinai.co/insights/en/ai-lead-scoring-model-drift-pipeline-quality details operations after the choice; those costs belong in the business case before the build.
Define exit from the start: export scores, versions, configuration, permitted datasets, evaluations, documentation, and decision history; disable the service without breaking CRM; and return to a rule or native score. If your company is deciding between configuring CRM and funding a custom layer, bring MAKINAI, through https://makinai.co/services/en/crm-ecommerce-commerce-transformation, one decision, a field-and-outcome export, and the current workflow. We can scope the smallest architecture worth testing.
The sources document product features and practices; they do not establish that one option will win in your company. The Ladder, gates, costs, example, and pilot are MAKINAI editorial recommendations to validate against your data, operations, and mature outcomes.