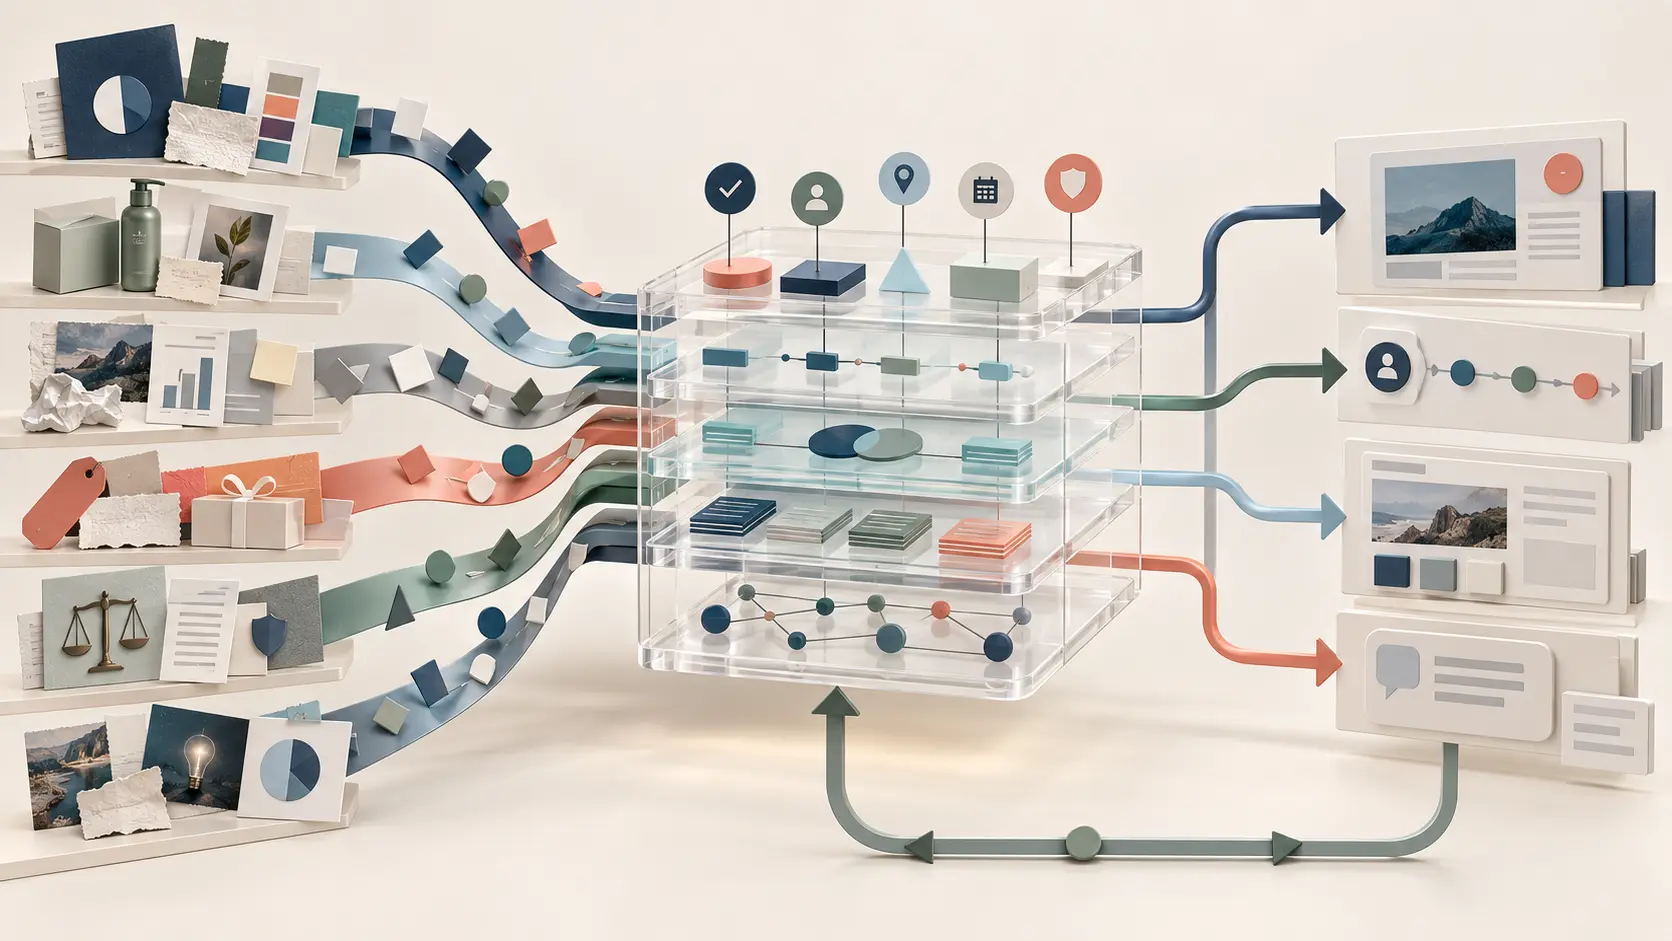
If two copilots give different answers about the same product, the next investment should not be another license. Build a marketing knowledge layer: governed facts, claims, offers, evidence, channel rules, and learnings, each with a source, owner, market, validity window, and permitted use. Then connect one valuable workflow—such as campaign briefing and production—and test whether the team reaches approved output faster with fewer factual corrections.
This layer is not a shared drive, a chatbot over PDFs, or a replacement DAM. It distinguishes authority from working material, resolves conflicting versions, restricts retrieval by market and date, exposes the source used, and creates a correction path. Retrieval-augmented generation can locate context. It cannot decide which claim is approved, who owns it, or when it expires.
Why another tool can create more rework
Marketing knowledge is often split across brand decks, product pages, sales enablement, legal notes, campaign workspaces, the CMS, CRM, PIM, DAM, and agency threads. One copilot retrieves an old price; another summarizes a superseded positioning statement; a regional team adapts a claim approved only for a different market. The model looks inconsistent because the knowledge system is inconsistent.
The failure appears downstream as bad copy or slow approval, but its cause is upstream: no authority hierarchy, fact owner, effective date, or market rule. Telling a model to use only correct information does not create those controls. A useful engagement makes knowledge part of operations rather than another attachment to a prompt.
The Marketing Knowledge Contract: nine fields
- Unit — one reusable fact, claim, offer, proof point, rule, or decision with enough context to stand on its own.
- Authoritative source — the system, document, or accountable expert that confirms it.
- Owner — the person responsible for validity and change approval.
- Market and language — where it may be used and which version is primary.
- Validity — effective date, expiration, or event that triggers review.
- Evidence — research, policy, specification, contract, or data supporting the assertion.
- Permitted use — channels, audiences, formats, limits, and explicit prohibitions.
- Dependencies — product, price, availability, rights, consent, or legal approval.
- Trace — version, derivation, published outputs that used it, and the correction path.
The contract can begin as a compact schema layered onto current sources. It does not require a company-wide content migration or a new platform. W3C PROV-O provides a reference model for representing entities, activities, agents, and derivation across systems. A marketing implementation can borrow the provenance concepts without adopting the entire ontology.
Scope one workflow, not the enterprise library
Start with one recurring campaign family, one product, and one market. List the questions that generate the most back-and-forth: which benefit can be claimed, what evidence supports it, which offer is active, which qualifier is mandatory, and which localization is allowed. A bounded slice reveals real conflicts, tests ownership, and proves integration before the program expands.
Use an API, rule, or transactional system for deterministic structured facts such as current price, availability, eligibility, and dates. Use semantic retrieval for unstructured material such as brand guidance, research, playbooks, and substantiation. Use generation to synthesize or adapt within retrieved limits. Putting every input in a vector store turns exact answers into unnecessary approximations.
The source-to-approved-output path
- 1. Inventory — map sources, versions, permissions, owners, and conflicts for the selected workflow.
- 2. Resolve authority — define which source wins, who decides exceptions, and what triggers review.
- 3. Structure — create contract units while preserving the original document and provenance link.
- 4. Retrieve — index only what is needed and filter by product, market, language, validity, permission, and use.
- 5. Answer or abstain — require internal citations and stop when evidence is missing, conflicting, or expired.
- 6. Approve and publish — show the reviewer the output, source, transformation, and risk; record the decision.
- 7. Learn — return corrections, unanswered questions, and asset performance to the knowledge backlog.
OpenAI documents vector-store workflows that chunk, embed, index, semantically search, and filter files by attributes. Google describes similar stages from ingestion and transformation through retrieval and generation. The plumbing is available across platforms. Authority, metadata, evaluation, and the operating routine remain implementation work.
Evaluate with questions designed to fail
Create an evaluation set before connecting the copilot to live work. Include straightforward questions, competing versions, an expired source, different markets, an unsupported claim, an instruction to bypass policy, and a legitimate question with no answer. For each case, record the expected source, acceptable response, reason to abstain, and competent reviewer. Re-run the same set when the model, index, prompt, or source changes.
- Retrieval — did the right source appear while the superseded version stayed out?
- Grounding — is every material assertion supported by the displayed source?
- Abstention — does the system stop when evidence, permission, or validity is missing?
- Consistency — do equivalent questions apply the same rule across the right channels and markets?
- Operations — can owners audit history and propagate a correction to dependent outputs?
The NIST Generative AI Profile treats evaluation and monitoring as lifecycle work. Here that means pre-deployment tests, production observation, source-change records, and a way to suspend the workflow. A polished demonstration using five friendly questions is not evidence of reliable operations.
An eight-week implementation scope
- Weeks 1–2: choose the workflow, product, and market; capture a baseline; inventory sources, conflicts, owners, and access.
- Weeks 3–4: define the knowledge contract, authority hierarchy, validity, permissions, ingestion, and deletion policy.
- Weeks 5–6: integrate one work interface, run in shadow mode, and execute the evaluation and adversarial cases.
- Weeks 7–8: release a bounded use case, measure quality and cycle time, repair propagation, document operations, and decide whether to expand, adjust, or stop.
The deliverable should include a source map, schema, prioritized content, authority rules, connectors, index and filters, evaluation set, logs, dashboard, runbook, exception queue, and maintenance plan. Eight weeks bounds the first workflow. It does not promise to clean the entire company knowledge estate or eliminate model errors.
What actually drives cost and architecture
Cost rises with the number of sources, formats, products, brands, markets, and languages; metadata quality; change frequency; role-based permissions; connectors; OCR; usage volume; model and infrastructure choices; human evaluation; privacy requirements; and how many downstream systems must receive corrections. The copilot license is one line item.
Centralization makes discovery simpler but expands migration and governance. Querying sources in place reduces copies but depends on uptime and APIs. Managed RAG accelerates a pilot while increasing platform dependency; a custom layer improves portability but adds operations. A knowledge graph can express complex relationships, yet it is often excessive for the first workflow. Choose the smallest architecture that preserves authority, filters, traceability, and evaluation.
Measure capability and outcome separately
- Quality — correct source, supported claim, conflict detection, appropriate abstention, and error by class.
- Operations — time to approval, review hours, rework, source age, and time to propagate a correction.
- Useful adoption — real tasks completed with the layer and approved outputs actually used, not logins.
- Business — campaign cycle time, cost per used asset, conversion, or revenue for the selected workflow, with a compatible baseline and comparison.
If answer quality improves but approval still stalls or the asset never reaches a channel, the bottleneck sits elsewhere. If the cycle speeds up but the commercial result does not move, review the proposition, distribution, or measurement before scaling. Attribute performance to the whole workflow, not the model in isolation.
Who owns the implementation
Marketing owns the use cases, quality standard, and outcome. Product, sales, and subject-matter experts own facts. Legal and privacy define limits where applicable. Content and brand maintain language and evidence. Technology owns identity, connectors, access, retrieval, and observability. The agency or consultancy should join those responsibilities, implement a live workflow, and leave clear ownership and operations—not just a chat demo.
When comparing proposals, ask the partner to demonstrate five situations: conflicting sources, an expired claim, an urgent correction, an unanswered question, and a market variant. Watch whether the system cites origin, respects filters, abstains, updates dependencies, and records the decision. That proof supports a real project without turning the article into a generic vendor scorecard.
Bring the problematic knowledge to the first conversation
Start with the first-workflow plan at https://makinai.co/insights/en/where-start-ai-marketing-90-day-first-workflow, connect the layer to production at https://makinai.co/insights/en/ai-campaign-production-workflow-brief-to-launch, and assess prerequisites at https://makinai.co/insights/en/assess-data-readiness-before-hiring-ai-company. To make the same evidence public and discoverable, see https://makinai.co/insights/en/company-search-absent-ai-answers-geo-plan. MAKINAI implements data, content, and intelligence architecture: https://makinai.co/services/en/data-content-intelligence-systems. Bring ten questions that produce conflicting answers and the sources used today; we can define the first workflow worth building.
The sources support retrieval components, RAG stages, provenance, and risk management. They do not prove that a particular knowledge layer will reduce rework or increase revenue. The contract, scope, metrics, and trade-offs are MAKINAI editorial recommendations that must be validated with real content, systems, and users.